
Repeat failure analysis using CMMS work order history
Just a 17-minute read
Repeat failure analysis identifies recurring equipment problems by linking maintenance records to distinct failure events, investigating their causes and checking corrective action effectiveness.
Start with consistent asset and failure information, count events rather than work orders, and compare performance under equivalent operating conditions. This makes maintenance history useful for deciding what to investigate and change.
Introduction
A pump receives a new seal, returns to service and leaks again. Each repair may have been completed correctly against its work order, yet the record still leaves an important question unanswered. Did the team remove the condition causing the leakage?
A computerized maintenance management system, or CMMS, provides the work history needed to investigate that question. The method below explains how to turn those records into a manageable review of recurring faults, without assuming that repeated symptoms prove a common cause.
What repeat failure analysis should establish
Repeat failure analysis is a structured review of recurring failure events affecting an asset, component or equipment population. Its purpose is to identify patterns worth investigating and establish whether subsequent actions reduce recurrence.
Keep four concepts separate.
- Symptom
What someone observed, such as abnormal vibration or a low flow alarm. - Failure mode
How the item failed to perform its required function, such as a valve failing to close. - Failure mechanism
The physical, chemical or other process producing the failure, such as fatigue or corrosion. - Cause
The circumstances that initiated or sustained that process, which require evidence to establish.
Replacing a component records a repair action. It does not, by itself, explain why the component failed.
Root cause analysis investigates the causal relationships behind a problem. Repeat failure screening helps decide where that investigation is needed. The American Society for Quality also places RCA within a wider improvement process, since identifying causes alone does not deliver a correction.
Reliable screening depends on reliable records. NIST research on maintenance work order data demonstrates how missing or inaccurate information can distort indicators and trend analysis.
Use consistent terminology, but retain technical distinctions. “Bearing noisy” and “bearing seized” should not automatically become the same failure mode. ManWinWin’s guidance on standardizing maintenance data provides broader context for managing this foundation.
ManWinWin Software is the result of 40+ years of experience and know-how

Get a personalized demo of ManWinWin CMMS
Please fill out the form and wait for one of our specialists to contact you to schedule a date at your convenience.
- Discover how ManWinWin solves your specific challenges.
- See ManWinWin’s core features, tailored to your needs.
- Gain best practices from the world’s most experienced CMMS company, specific for your success.
- Discover your ideal ManWinWin license, investment, and timing of implementation.
A practical repeat failure analysis workflow
Use four connected steps to move from repair records to verified improvement. Pilot the process on one equipment family or production area before extending it across sites.
1. Define the events
Build the review around distinct failure events rather than the number of corrective work orders. One breakdown may generate separate mechanical, electrical and contractor orders. Conversely, one standing work order may contain several failures. Reconcile those records before calculating recurrence. For each event, capture the information needed to interpret it.
- Asset identifier and affected component
- Event date, time and associated work order references
- Required function and observed loss of performance
- Symptom, failure mode and mechanism where established
- Operating conditions, readings and relevant recent changes
- Downtime, repair actions, labour and materials
- Cause status, distinguishing unknown, suspected and confirmed
Exclude routine preventive work from failure counts. Assess defects discovered during inspections against the agreed functional failure criteria rather than automatically counting every finding as a failure.
Choose an initial review window suited to the equipment’s duty and expected recurrence. A frequently cycling conveyor and an annually operated standby system need different observation periods.
ISO 14224 provides a reference for collecting equipment, failure and maintenance data. Its formal scope covers petroleum, petrochemical and natural gas operations. Other industries should assess how its principles fit their equipment rather than assume universal applicability.
2. Prioritise the losses
Rank recurring problems by their consequences as well as their frequency. A Pareto chart orders categories by a selected measure. Create separate views for event count, downtime and direct repair cost. Combining them into an unexplained score can hide the reason an asset deserves attention.
An SMRP case study illustrates the use of recorded failure histories to examine frequency and maintenance cost. Treat it as an application example, not a universal performance benchmark.
Hypothetical screening example:
- During the same review period, one conveyor experiences eight brief stoppages totalling two hours. A process pump experiences three seal failures totalling eighteen hours.
- The conveyor leads the frequency list. The pump leads the downtime list. Neither ranking replaces a criticality assessment. A single failure affecting a protective function may require investigation before either asset.
- For each shortlisted problem, write a neutral statement describing the asset, failed function, recurrence, operating context and consequence. “Pump P101 lost containment at the mechanical seal during three separate operating events” is more useful than “poor maintenance caused repeated leaks”.
- Record gaps in evidence alongside the ranking. Missing downtime should remain visibly missing rather than being entered as zero.
3. Test the causes
Use maintenance failure analysis to test explanations against evidence. Reconstruct the sequence before and after each event. Compare operating conditions, recent interventions, component specifications, physical findings and repair methods. Involve the technicians who performed the work and the operators who observed the fault.
For the hypothetical pump, repeated seal replacement does not prove defective seals. Candidate explanations might involve installation, operating conditions, material suitability or the seal support arrangement. Investigate the candidates that fit the equipment and evidence.
A practical investigation should answer three questions.
- What evidence supports each proposed cause?
- What evidence contradicts it?
- What inspection, measurement or test would distinguish the remaining explanations?
Use the 5 Whys to explore a simple causal chain, but do not force the investigation to end after five questions. More complex events may need specialist examination or several branches of analysis. Keep unconfirmed causes explicitly provisional. “Operator error” also requires further investigation into procedures, interfaces, working conditions and controls. The UK Health and Safety Executive explains how maintenance errors can be anticipated and managed.
Preserve useful evidence during restoration wherever safe and practical. Field reporting through the ManWinWin maintenance app can help keep work information connected to the equipment record.
4. Verify the actions
Define how an action will be evaluated before marking the investigation complete. Separate restoration from prevention. Replacing the leaking seal restores the equipment. Correcting an evidenced installation or operating problem addresses recurrence.
For every selected action, record an owner, completion date, implementation evidence and acceptance criteria. Give the effectiveness review its own date or operating exposure requirement. Compare performance under similar duty. Calendar time alone can mislead when production hours, starts, load or environmental conditions change.
Hypothetical measurement example:
- Before an intervention, the pump experiences three comparable seal failure events during 3,000 operating hours. That is one event per 1,000 operating hours.
- After the intervention, it operates for 1,500 hours without another recorded seal failure. This is encouraging evidence, but the observation period does not prove permanent elimination. Record the operating conditions and continue monitoring.
- Track the targeted failure mode alongside downtime and repair resources. Confirm that apparent improvement does not reflect reduced use, incomplete reporting or a transfer of failures to another component.
- Where findings justify changes, update the job instructions, operating requirements or preventive tasks. Adding more frequent maintenance without an evidenced reason merely schedules more work.

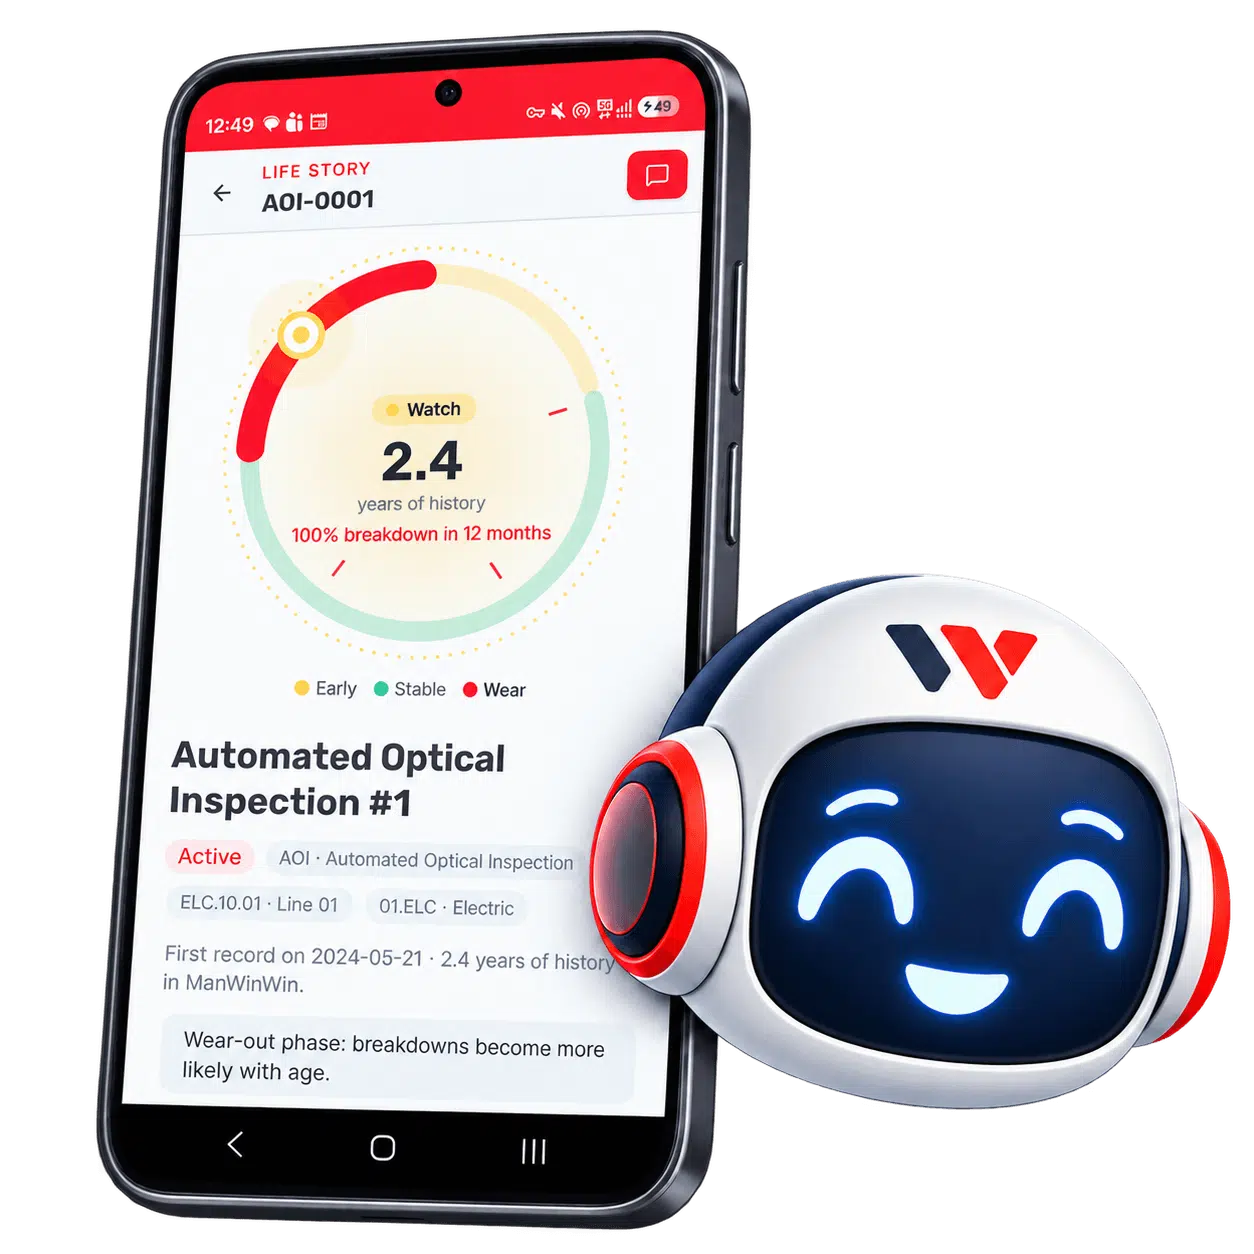
Meet Winston.
The AI that knows your maintenance.
Winston knows your ManWinWin. Ask in plain words and get exact answers from your own data, at your desk, on the shop floor or hands-free. In the Winston Help Center, learn ManWinWin with guides and videos and get support from our team.

Frequently asked questions
Practical decisions when applying the workflow
dummy
How many failures should trigger an investigation?
Set triggers according to consequence, recurrence and available evidence. A repeated minor fault may justify a focused review, while one serious event can require immediate investigation. Use local thresholds as screening rules rather than universal reliability standards.
Can the same symptom have different causes?
Yes. A motor trip may arise from different electrical, mechanical or process conditions. Similar symptoms justify comparison, but a common cause requires supporting evidence.
What if historical work orders contain only brief notes?
Start with a limited, documented cleanup of the selected assets. Retain the original notes, record classification uncertainty and ask knowledgeable technicians to review ambiguous entries. Leave unresolved records unknown rather than manufacturing precision.
Should failure frequency be compared across different machines?
Compare equipment performing sufficiently similar duties, and account for exposure such as operating hours, starts or cycles. Also consider load, environment, age and reporting quality. Raw event counts alone can make heavily used equipment appear less reliable simply because it operates more.
Does every corrective work order represent an equipment failure?
No. Corrective work can address a detected defect before the required function is lost, and several orders can relate to one failure. Establish the event boundary and functional criteria before using work order records to calculate reliability indicators.
Can a CMMS confirm the root cause automatically?
A CMMS can organize records and help reveal patterns. Confirming a cause still requires appropriate evidence and engineering judgment. Treat automated suggestions as investigation inputs that need validation.
Conclusion
Make each investigation change the maintenance record
Start with one equipment family, reconcile its failure events and identify the problems with the greatest operational consequences. Test the causes, assign corrective actions and review effectiveness under comparable duty.
ManWinWin’s verified maintenance history, work order and reporting capabilities support this process by connecting equipment records with completed work, labour, materials, supporting documents and performance information. The practical requirement is to use those records consistently and retain the evidence behind each decision.
ManWinWin is a globally proven CMMS platform positioned between lightweight SaaS tools and heavy enterprise EAM suites, offering structured, scalable, and practical maintenance management for industrial and multi-site organizations worldwide.
Ready to take your maintenance to the next level?
Trusted in over 120 countries – join the global maintenance movement with ManWinWin Software







About the Author
José Fernandes is the Managing Partner at ManWinWin Software (Navaltik Management), leading company in maintenance management consultancy and CMMS (Computerized Maintenance Management System) solutions.
With a technical background in industrial organization, José Fernandes has been with Navaltik since the 1990s, progressing from consultant to strategic leader and a key figure in the development of the ManWinWin software.
Throughout his career, he has overseen hundreds of maintenance system implementations across more than 30 countries, including regions in Africa, Australia, the Middle East, and East Asia.