
Why 79% of manufacturers still struggle with unplanned downtime in 2026
Just a 24-minute read
Equipment stops without warning. Production halts. Costs spike. In 2026, unplanned downtime in manufacturing remains one of the most expensive — and preventable — operational failures.
Here is why it keeps happening and what maintenance engineering tells us to do differently.
Table of contents
1. The real cost of unplanned downtime: beyond the obvious numbers
2. The four root causes no one wants to talk about
3. What actually works: the technical shift from reactive to predictive maintenance
4. Frequently asked questions on unplanned downtime and maintenance management
Conclusion: structured maintenance management is the variable that changes the outcome
Introduction
According to a 2023 Siemens study, unplanned downtime costs industrial manufacturers an average of $260,000 per hour, and the global manufacturing sector loses an estimated $50 billion per year to unplanned equipment failures alone (source: https://press.siemens.com/global/en/pressrelease/siemens-study-manufacturers-lose-estimated-50b-annually-machine-downtime). That is not a new problem. What is new — and frankly uncomfortable — is that by 2026, 79% of manufacturers still report recurring unplanned downtime despite decades of investment in reliability engineering, predictive technologies, and digital maintenance tools. Something structural is broken, and it is not the machines.
The gap between technology availability and operational performance has never been wider. Most plants today have condition monitoring sensors, vibration analysis tools, and CMMS platforms in place. Yet equipment still fails unexpectedly, production lines still stop without warning, and maintenance teams still spend the majority of their shift reacting rather than preventing. The problem is not a lack of tools. It is a chronic failure to operationalize maintenance knowledge — to turn data, history, and engineering judgment into repeatable, system-driven routines that prevent failures before they interrupt production.
1. The real cost of unplanned downtime: beyond the obvious numbers
Most maintenance managers can tell you what an unplanned stoppage costs in direct production loss. Few can tell you the full number — because the full number is built from layers that rarely appear on the same report.
Direct costs are the obvious ones: lost throughput, overtime labor, emergency spare parts, and expedited logistics. A pump failure on a critical line is not just the repair cost; it is the production gap, the overtime to recover schedule, and the premium shipping charge for the part that was not in stock. In high-volume manufacturing, this alone can run to tens of thousands per hour.
Indirect costs are where the real damage accumulates. Quality defects spike immediately after restarts — thermal cycling, pressure transients, and reassembly variations are all known failure precursors that rarely get tracked back to the original stoppage event. Customer penalties for missed delivery windows, accelerated asset degradation from stress-restart cycles, and the organizational cost of constant firefighting — these rarely appear in a downtime cost report, but they are measurable and often exceed the direct costs by a factor of two or three.
A 2022 Aberdeen Group study found that best-in-class manufacturers with mature maintenance programs report 90%+ planned maintenance ratios, while average performers sit below 55% (source: https://www.aberdeen.com/). The 35-point gap in planned vs. reactive maintenance is not a technology gap — it is a management systems gap. Plants that close it do so by treating maintenance as a production discipline, not a support function.
The financial benchmark: For a mid-size automotive parts plant running two shifts, reducing unplanned downtime from 8% to 3% of available production hours typically translates to an additional 400–600 production hours per year — the equivalent of adding a full month of capacity without capital investment.
ManWinWin Software is the result of 40+ years of experience and know-how

With thousands of users in 120+ countries in the World. Created by Portuguese Engineers has been improved with implementations, and listening to thousands of clients worldwide using the system.
Get a personalized demo of ManWinWin CMMS
Please fill out the form and wait for one of our specialists to contact you to schedule a date at your convenience.
- Discover how ManWinWin solves your specific challenges.
- See ManWinWin’s core features, tailored to your needs.
- Gain best practices from the world’s most experienced CMMS company, specific for your success.
- Discover your ideal ManWinWin license, investment, and timing of implementation.
2. The four root causes no one wants to talk about
Unplanned downtime is never random. Equipment does not fail without reason. After hundreds of CMMS implementation projects across multiple industries, the same four structural causes appear repeatedly — each one preventable with the right maintenance system in place.
1. Inadequate failure mode mapping
Most plants have a preventive maintenance (PM) schedule. Very few have a failure mode and effects analysis (FMEA) driving that schedule. When PM tasks are assigned based on OEM recommendations or maintenance manager intuition rather than documented failure modes, the maintenance program systematically misses the actual degradation patterns of the equipment in that specific operating context. A pump running against a higher-than-design differential pressure will fail through a completely different failure mode than the same pump at nominal conditions — and a generic PM schedule will not catch it.
The fix is not complex: map the top 20 critical assets to their actual failure modes, rank them by failure probability and consequence, and rebuild the PM tasks around that analysis. In practice, most plants skip this step because it takes engineering time upfront. The cost of skipping it is measured in years of reactive maintenance.
2. Work order backlogs that never close
A persistent work order backlog is the clearest leading indicator of future unplanned downtime. When corrective maintenance is logged but deferred — because production pressure, resource constraints, or poor scheduling prevents timely execution — the known defects accumulate until they trigger failures. Industry data consistently shows that backlog-to-workforce ratios above 3:1 (three weeks of work for one week of capacity) are associated with significantly higher unplanned downtime rates.
The discipline required here is twofold: capture all defects systematically through a work order system, and enforce backlog review as a weekly operations-maintenance joint decision. Backlogs are not a maintenance problem — they are a production priority problem that maintenance happens to own the reporting on.
3. Spare parts management disconnected from failure history
Emergency spare parts procurement is one of the most expensive and avoidable costs in maintenance. It happens when the failure history of an asset is not connected to the spare parts inventory policy. In a CMMS-mature environment, every work order that consumes a spare part updates the consumption rate, which drives the reorder point calculation. In most plants, these two systems — maintenance history and parts inventory — are either not integrated or not actively managed together.
The result is predictable: common failure components are either overstocked (capital tied up unnecessarily) or understocked (production stopped waiting for a part). A 2021 Plant Engineering survey found that 42% of unplanned downtime events involved waiting for parts — not waiting for technicians (source: https://www.plantengineering.com/). That is an inventory management failure, not a maintenance failure.
4. No distinction between chronic and sporadic failures
Sporadic failures get attention because they are dramatic. Chronic failures — the assets that stop frequently but briefly, the equipment that needs adjustment every week, the line that loses 2% OEE every shift to minor stoppages — are normalized and ignored. This is a critical analytical blind spot.
Chronic failures are typically higher-priority targets for reliability improvement than sporadic ones, because their cumulative production impact is larger and their root causes are usually addressable with focused engineering attention. Total Productive Maintenance (TPM) methodology specifically targets chronic losses through focused improvement (kobetsu kaizen) activities. Without a CMMS system that can generate chronic failure reports — assets ranked by failure frequency rather than failure severity — maintenance teams will always chase the dramatic event and leave the chronic losses in place.

3. What actually works: the technical shift from reactive to predictive maintenance
Shifting from reactive to predictive maintenance is not a technology purchase decision. It is a data maturity journey that takes between 18 and 36 months in most industrial environments, and it requires a functional foundation that many plants do not yet have.
The foundation is condition data — and the precondition for useful condition data is consistent, structured maintenance history. A vibration sensor on a bearing tells you the current condition. Historical work order data on that bearing tells you the failure trajectory, the typical time-to-failure, and the maintenance intervention that actually worked. Without the history, the sensor data is noise. With the history, it becomes a decision trigger.
- Stage 1 — Failure history capture: Every corrective work order must record the failure mode, the failed component, the probable root cause, and the actual repair performed. This is not optional. It is the data that makes everything else possible. In most plants, this discipline takes 6–12 months to establish consistently.
- Stage 2 — PM optimization: Once failure history exists, PM frequencies can be validated against actual failure patterns. Tasks that never catch anything get extended or eliminated. Tasks that consistently find defects get tightened. This is reliability-centered maintenance (RCM) in practice — not as a consulting project, but as an ongoing management discipline embedded in the CMMS.
- Stage 3 — Condition-based triggers: With optimized PMs and reliable history, condition monitoring (vibration analysis, oil analysis, infrared thermography, ultrasonic inspection) can be deployed strategically on critical assets. The condition data does not replace scheduled maintenance — it informs it. Readings outside established baselines trigger work orders. Readings within tolerance extend the maintenance interval. This is predictive maintenance as an operational system, not a pilot program.
- Stage 4 — Reliability KPIs as production metrics: Mean Time Between Failures (MTBF), Mean Time To Repair (MTTR), planned maintenance percentage (PMP), and Overall Equipment Effectiveness (OEE) must be reviewed weekly in joint maintenance-production meetings. These are not internal maintenance metrics. They are production performance indicators that maintenance happens to generate. Plants where reliability KPIs are owned by operations — not just reported by maintenance — consistently outperform those where they are not.
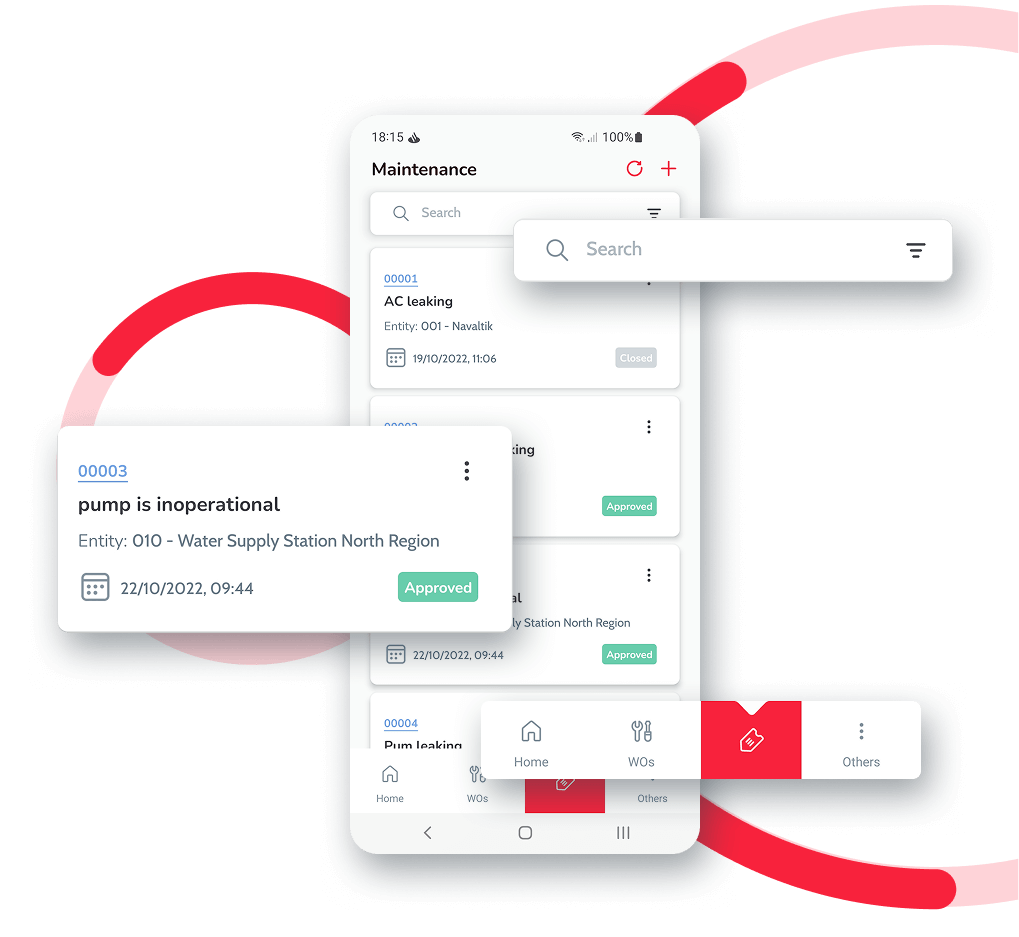
The technical literature supports a clear hierarchy of maintenance strategy effectiveness: predictive > preventive > reactive. What the literature does not always make clear is that predictive maintenance is not accessible without a functional preventive maintenance program, and a functional preventive maintenance program is not accessible without structured work order management. The sequence matters. Skipping steps is expensive.
Join ManWinWin Software, the world’s most experienced company in CMMS!
Choose a better way to manage your Maintenance
Watch or book a Demo
Watch a recorded demo or get to know ManWinWin guided by one of our experts.
Use ManWinWin free version
Free forever industrial maintenance management software up to 100 Assets. Start today!
4. Frequently asked questions on unplanned downtime and maintenance management
Answers for maintenance engineers and plant managers working on reliability improvement
dummy
1. What is unplanned downtime and how is it measured?
Unplanned downtime is any production stoppage caused by an equipment failure or process fault that was not scheduled in the maintenance plan. It is measured as a percentage of available production time — total unplanned downtime hours divided by total available hours in a given period. In OEE (Overall Equipment Effectiveness) calculation, unplanned downtime contributes directly to the Availability component. A plant with 5% unplanned downtime rate is losing 1 in every 20 available production hours to unexpected failures. Industry benchmarks for world-class manufacturing typically target unplanned downtime below 2% of available time.
2. Why do preventive maintenance programs fail to prevent unplanned failures?
PM programs fail to prevent unplanned failures for three primary reasons. First, PM tasks are often based on OEM default intervals rather than actual failure history in the specific operating context — which means the tasks address the wrong failure modes at the wrong frequency. Second, PM execution compliance is rarely enforced: tasks are skipped or deferred under production pressure, and no one tracks the cumulative compliance rate. Third, PM programs are static — they are not updated when failure patterns change, when assets age, or when operating conditions shift. A PM program that was designed five years ago and has not been revised is almost certainly not aligned with current equipment reliability behavior.
3. What is the difference between MTBF and MTTR, and why do both matter?
MTBF (Mean Time Between Failures) measures the average operating time between failure events on a given asset. A higher MTBF indicates better reliability — the asset runs longer before failing. MTTR (Mean Time To Repair) measures the average time from failure detection to restored operation. A lower MTTR indicates better maintainability — the team can recover faster when failures occur. Both metrics matter because they address different dimensions of the downtime problem. Reducing unplanned downtime requires either increasing MTBF (preventing failures from occurring) or reducing MTTR (recovering faster when they do). Mature maintenance programs actively manage both. CMMS systems like ManWinWin can track both metrics automatically from work order data, enabling trend analysis at the asset, system, and plant level.
4. When should a manufacturer implement condition monitoring versus relying on scheduled PM?
Condition monitoring is appropriate for assets that meet three criteria: critical to production (high consequence of failure), technically monitorable (the relevant failure modes produce measurable physical signals), and economically justifiable (the cost of monitoring is lower than the cost of failure). For most plants, this applies to 10–20% of the asset base — rotating equipment, power distribution components, critical instrumentation, and load-bearing structures. For the remaining 80%, optimized scheduled PM is more cost-effective. The mistake is applying condition monitoring indiscriminately or, worse, deploying sensors without the maintenance history needed to interpret the data meaningfully. Condition monitoring without a CMMS foundation generates data without actionable context.
5. How long does it take to measurably reduce unplanned downtime with a CMMS?
Based on structured implementation experience across multiple industries, measurable improvements in unplanned downtime typically appear within 6–12 months of a properly structured CMMS deployment. The first improvements come from work order visibility and backlog management — defects get captured and addressed before they escalate. The second wave of improvement, from PM optimization and failure history analysis, typically arrives between 12 and 24 months. Full predictive maintenance capability, built on 24+ months of clean data, is a 3-year journey for most organizations. Plants that expect immediate results from a CMMS often underinvest in the data quality and process discipline that determine actual outcomes. The technology accelerates the journey; it does not substitute for it.
6. What maintenance KPIs should a plant track to manage unplanned downtime?
The minimum viable set of maintenance KPIs for managing unplanned downtime includes: (1) Planned Maintenance Percentage (PMP) — target above 85% to ensure the majority of work is scheduled rather than reactive; (2) PM Compliance Rate — percentage of planned PMs completed on schedule, target above 95%; (3) MTBF by critical asset — tracked monthly with trend analysis; (4) MTTR by failure category — identifies bottlenecks in the repair process; (5) Work Order Backlog Age — aged backlog report distinguishing active defects from deferred low-priority tasks; (6) Unplanned Downtime Rate — total unplanned hours as percentage of available time, reviewed weekly. These six metrics, maintained consistently in a CMMS and reviewed in joint maintenance-production meetings, give a complete operational picture of reliability performance.
Discover ManWinWin services in maintenance management consulting

Implementation
The implementation consultancy is the component that turns a good software into a good solution.
Training
Training is the component that consolidates and sustains the solution on the client.
Conclusion: structured maintenance management is the variable that changes the outcome
Unplanned downtime in 2026 is not a technology problem. Every tool needed to prevent most equipment failures already exists — condition monitoring sensors, vibration analysis, OEE tracking, predictive algorithms. The persistent 79% failure rate exists because most organizations have not built the underlying management system that makes those tools effective.
The sequence is clear: structured work order discipline comes first, then failure history, then PM optimization, then condition-based maintenance, then predictive capability. Skipping steps is expensive. Building on a weak foundation is more expensive. The plants that close the gap between average and world-class reliability performance do so by treating maintenance as a production discipline — with owned KPIs, enforced compliance, and continuous improvement built into the daily operating rhythm.
The choice of CMMS platform matters more than most organizations realize — not because of feature lists, but because of structural fit. Lightweight SaaS tools lack the asset hierarchy depth and multi-site capability needed for industrial environments. Heavy enterprise EAM suites require implementation timelines and IT resources that most manufacturing operations cannot absorb. The operational sweet spot is a structured, scalable CMMS designed specifically for industrial and multi-site maintenance management.
ManWinWin is a globally proven CMMS platform, deployed across hundreds of industrial and multi-site organizations worldwide. Positioned between lightweight SaaS tools and heavy enterprise EAM suites, ManWinWin delivers structured, scalable, and practical maintenance management — built for the operational realities of manufacturing, facilities, and critical infrastructure.
Key capabilities for unplanned downtime reduction:
- Asset hierarchy management mapped to failure modes and criticality classification
- Preventive and corrective work order management with full failure history capture
- MTBF, MTTR, PMP, and backlog KPI dashboards updated in real time from work order data
- Spare parts management integrated with maintenance history for optimized inventory policy
- Multi-site deployment with centralized reporting and localized maintenance execution
See how ManWinWin helps manufacturers build predictive maintenance programs
| Reference context | URL |
| $260k/hr downtime cost — Siemens | https://press.siemens.com/global/en/pressrelease/siemens-study-manufacturers-lose-estimated-50b-annually-machine-downtime |
| 42% downtime waiting for parts — Plant Engineering | https://oxmaint.com/blog/post/top-10-reduce-unplanned-downtime-manufacturing-ai-iot |
Ready to take your maintenance to the next level?
Trusted in over 120 countries – join the global maintenance movement with ManWinWin Software



About the Author
José Fernandes is the Managing Partner at ManWinWin Software (Navaltik Management), leading company in maintenance management consultancy and CMMS (Computerized Maintenance Management System) solutions.
With a technical background in industrial organization, José Fernandes has been with Navaltik since the 1990s, progressing from consultant to strategic leader and a key figure in the development of the ManWinWin software.
Throughout his career, he has overseen hundreds of maintenance system implementations across more than 30 countries, including regions in Africa, Australia, the Middle East, and East Asia.

